Tag: incident response

Attaching Evidence to Alerts: an Enrichment Sidecar for Alertmanager
 Daniil Romashov | | Alertmanager, incident response, log management, observability, Prometheus, Slack
Every on-call engineer knows the ritual. A page lands in Slack: the 5xx rate on a service is above the threshold. The message tells you that something is wrong and nothing about ...

Availability Should Follow the Workload, Not the Infrastructure
 Don Boxley | | application recovery, automated remediation, cloud resilience, devops, disaster recovery, High availability, incident response, intelligent operations, kubernetes, mttr, operational automation, operational intelligence, platform engineering, platform maturity, production incidents, production resilience, self-healing systems, site reliability engineering, SRE, workload availability
Platform engineering has automated deployment but not recovery. The next maturity curve is intelligent operations that automate routine production decisions and resilience ...

How to Move AI SRE Agents From Demo to Production
 Andrey Pokhilko | | agentic AI, AI agents, AIOps, incident response, observability, site reliability engineering
An AI agent that works on an engineer’s laptop can feel like a breakthrough. It can read logs, query observability tools, inspect cloud resources and connect a failed deployment to a bad ...

The Observability Tax: When Monitoring Costs Exceed Downtime Costs
 Muhammad Yawar Malik | | cloud costs, data retention, devops, Distributed Tracing, FinOps, incident response, infrastructure monitoring, logs, metrics, observability, observability costs, observability strategy, OpenTelemetry, platform engineering, SRE, telemetry, telemetry costs, traces
Observability costs can spiral when teams collect more telemetry than they actually use. A more mature approach prioritizes the data that directly improves incident detection, diagnosis and recovery ...

The Three Tiers of Agentic Incident Response: When to Trust AI Autonomy
 Neel Shah | | agentic AI, AI agents, AI Governance, AI operations, AIOps, automation guardrails, autonomous remediation, devops, human-in-the-loop, incident management, incident response, mttr, observability, production reliability, Runbooks, site reliability engineering, SRE
A three-tier model for agentic incident response balances AI automation with human oversight, matching autonomy to risk, reversibility, blast radius and diagnostic confidence ...

GitHub’s August Outages Show Growth Is Outpacing Infrastructure
 Tom Smith | | AI coding agents, capacity planning, CI/CD, cloud infrastructure, developer infrastructure, developer productivity, devops, distributed systems, github, GitHub Actions, GitHub Copilot, GitHub outages, incident response, platform engineering, platform reliability, production resilience, retry storms, service availability, software delivery, Software Supply Chain
GitHub's August 2026 report details five outages tied to Actions and Copilot growth outpacing infrastructure. Here's what platform teams should know ...

Observability’s Gaslighting Problem: “Send Less Data” Isn’t a Strategy
 Noam Levy | | agentic development, AI agents, AI-assisted development, cardinality, data retention, developer observability, devops, incident response, logs, metrics, observability, observability costs, observability strategy, Runtime Visibility, software reliability, SRE, telemetry, Telemetry Optimization, telemetry sampling, traces
A familiar pattern is emerging in observability conversations. As telemetry volumes grow and costs rise, the default recommendation is often to collect less data: Sample more, retain less, index selectively, filter earlier, ...

Beyond Log Search: What We Learned Building a RAG-Based Incident Diagnosis System
 Abhimanyu Garg | | AI for SRE, AI hallucinations, AI incident diagnosis, AIOps, devops, devops automation, FAISS, incident management, incident remediation, incident response, knowledge management, knowledge retrieval, LLM grounding, LLM incident response, observability, postmortems, production AI, RAG AIOps, re-ranking, retrieval-augmented generation, root cause analysis, Runbooks, semantic search, SRE
A RAG-based AIOps framework can cut incident diagnosis time by grounding LLM reasoning in real runbooks, tickets and postmortems, improving root-cause accuracy while giving SREs source-backed answers they can trust ...

Reducing MTTR: A Practical Guide to Correlating Incidents with AIOps
Neel Shah | | AI for SRE, AI observability, AI-driven incident correlation, Aiden AI Copilot, Aiden for SRE, AIOps, alert correlation, alert fatigue, alert storms, automated remediation, automated root cause analysis, devops, Distributed Tracing, grafana, incident correlation, incident management, incident response, Jaeger, Loki, mean time to resolution, metrics logs traces, mttr, observability, ObserveNow, on-call automation, pattern-based correlation, Prometheus, root cause analysis, service dependency mapping, SRE automation, telemetry correlation, topology-aware correlationAI-driven incident correlation helps SRE and DevOps teams reduce alert noise, identify root causes faster and improve MTTR by connecting related metrics, logs and traces ...
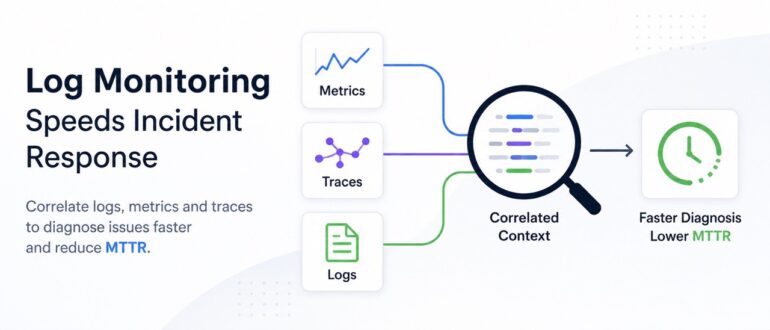
Why Log Monitoring Is the Missing Link in Most Incident Response Workflows

Modern engineering teams have invested heavily in observability. Dashboards are populated, alerts are configured, on-call rotations are set. Yet when production incidents occur, the average time to resolution hasn't dropped nearly as ...

From Reactive Monitoring to AI-Driven Operational Intelligence
 Sneha Gullapalli | | AI observability, Amazon Q, Apache Iceberg, automated root cause analysis, AWS CloudWatch, AWS operations, CloudWatch Logs, DevOps observability, Distributed Tracing, Five Whys, GenAI observability, incident response, LLM monitoring, log lake, MTTR reduction, operational intelligence, proactive monitoring., RAG latency, S3 Tables, token usage monitoring
Traditional monitoring often meant chasing alerts and toggling between dashboards after an issue had already impacted users. AWS CloudWatch — long the backbone of metrics, logs and traces on AWS — is ...

On-Call: The Silent Force Shaping Engineering Culture

There is a silent force shaping engineering culture inside every technology organization. It affects productivity, team morale, psychological safety, and long-term retention. And yet, it is rarely discussed in executive meetings or ...